01Know
Your AI spend, under control.
Explore the core capabilities that make Brutor AI a complete FinOps solution for AI.
02Optimize
Every governed call runs at the lowest cost.
03Agents
No runaway agents. No burned budgets.
04Tokenomics
See which workloads stay affordable as you scale.
What you route and what you buy, on one ledger.
While other providers typically provide economics for traffic you route through their gateways, Brutor AI offers much more:
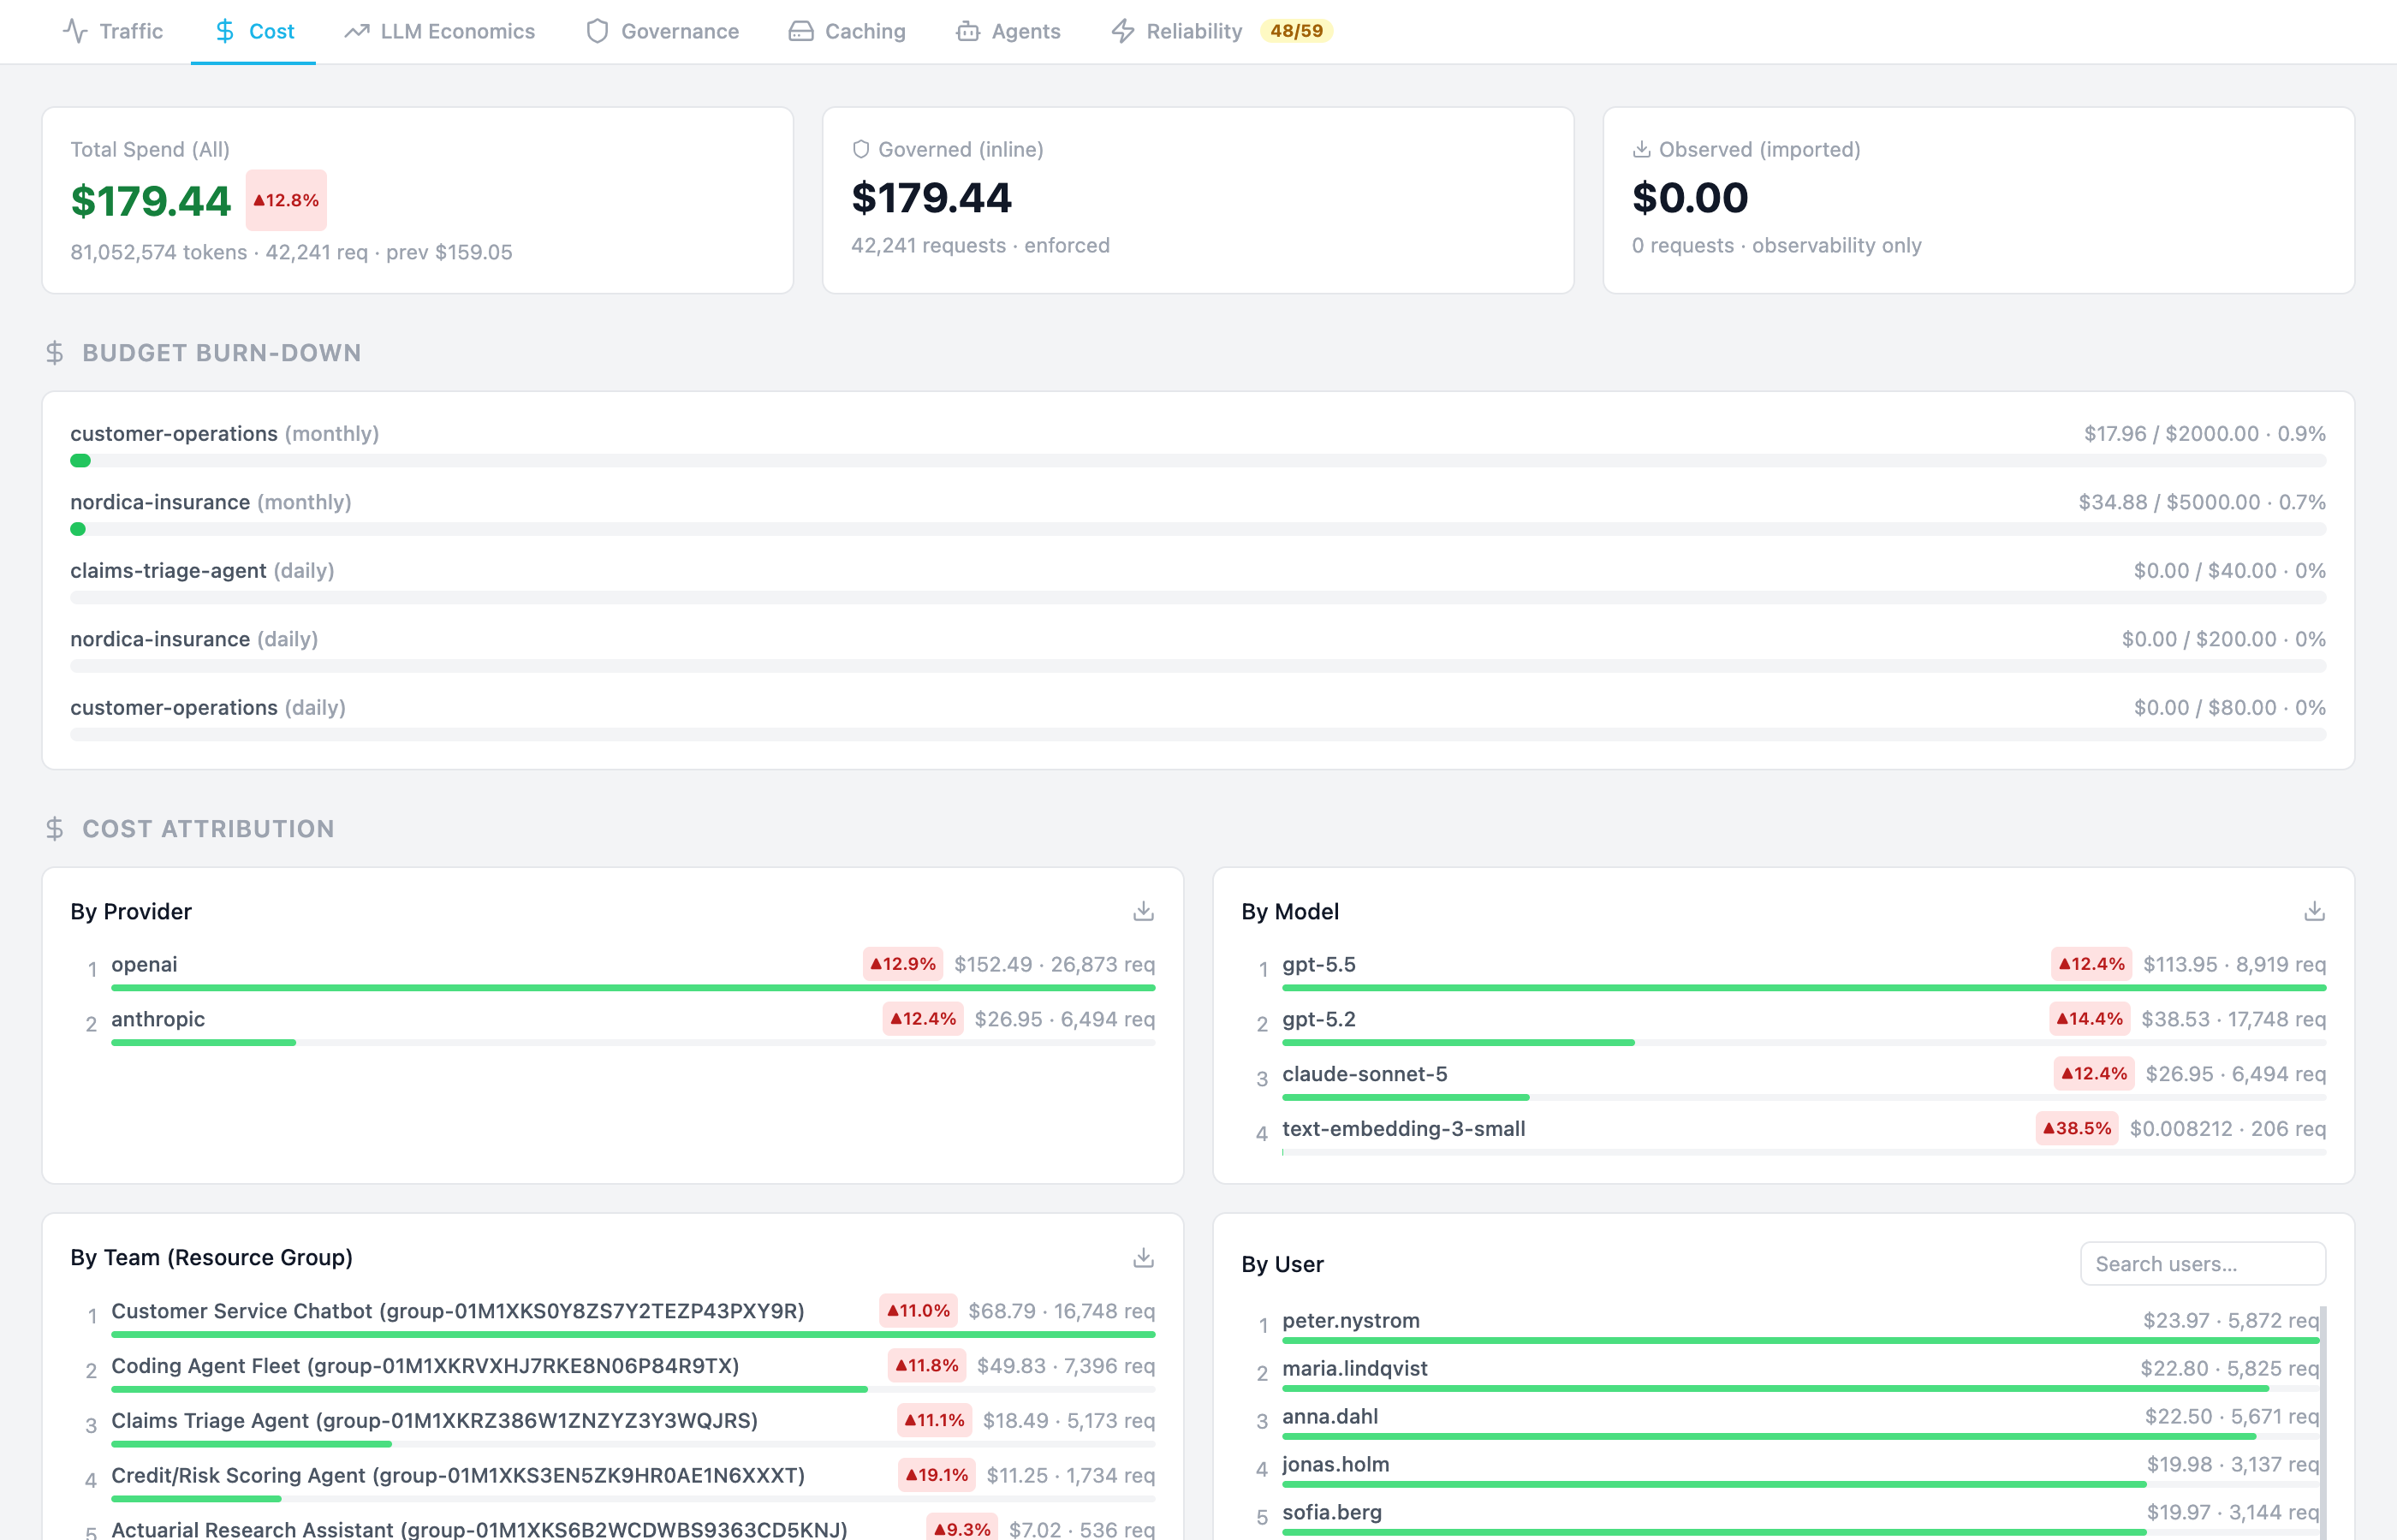
- Traffic governed through the Brutor AI Gateway. Metered, priced, and enforced as it flows: budgets, token and request limits per team, project, or agent, checked before the call for LLM and MCP traffic.
- Bought AI, on the same ledger. Spend with Anthropic, OpenAI, Google, and Microsoft is tracked alongside routed spend, with budget warnings on both.
- Shadow AI Discovery. Find AI traffic that you do not have under control, so you can govern it and stay on top of AI spend.
- All AI costs attributed. Tied to team, user, model, and agent, with burn-down and run-rate, so you can charge back and forecast.
Governed AI calls at the lowest price possible
Brutor AI Gateway makes routed traffic cheaper, automatically, on every request. The built-in optimizations:
- Smart model routing. Set a routing group to lowest cost, and each call goes to the cheapest eligible model.
- Batch processing. Large, non-urgent jobs run at the providers’ lower batch rates.
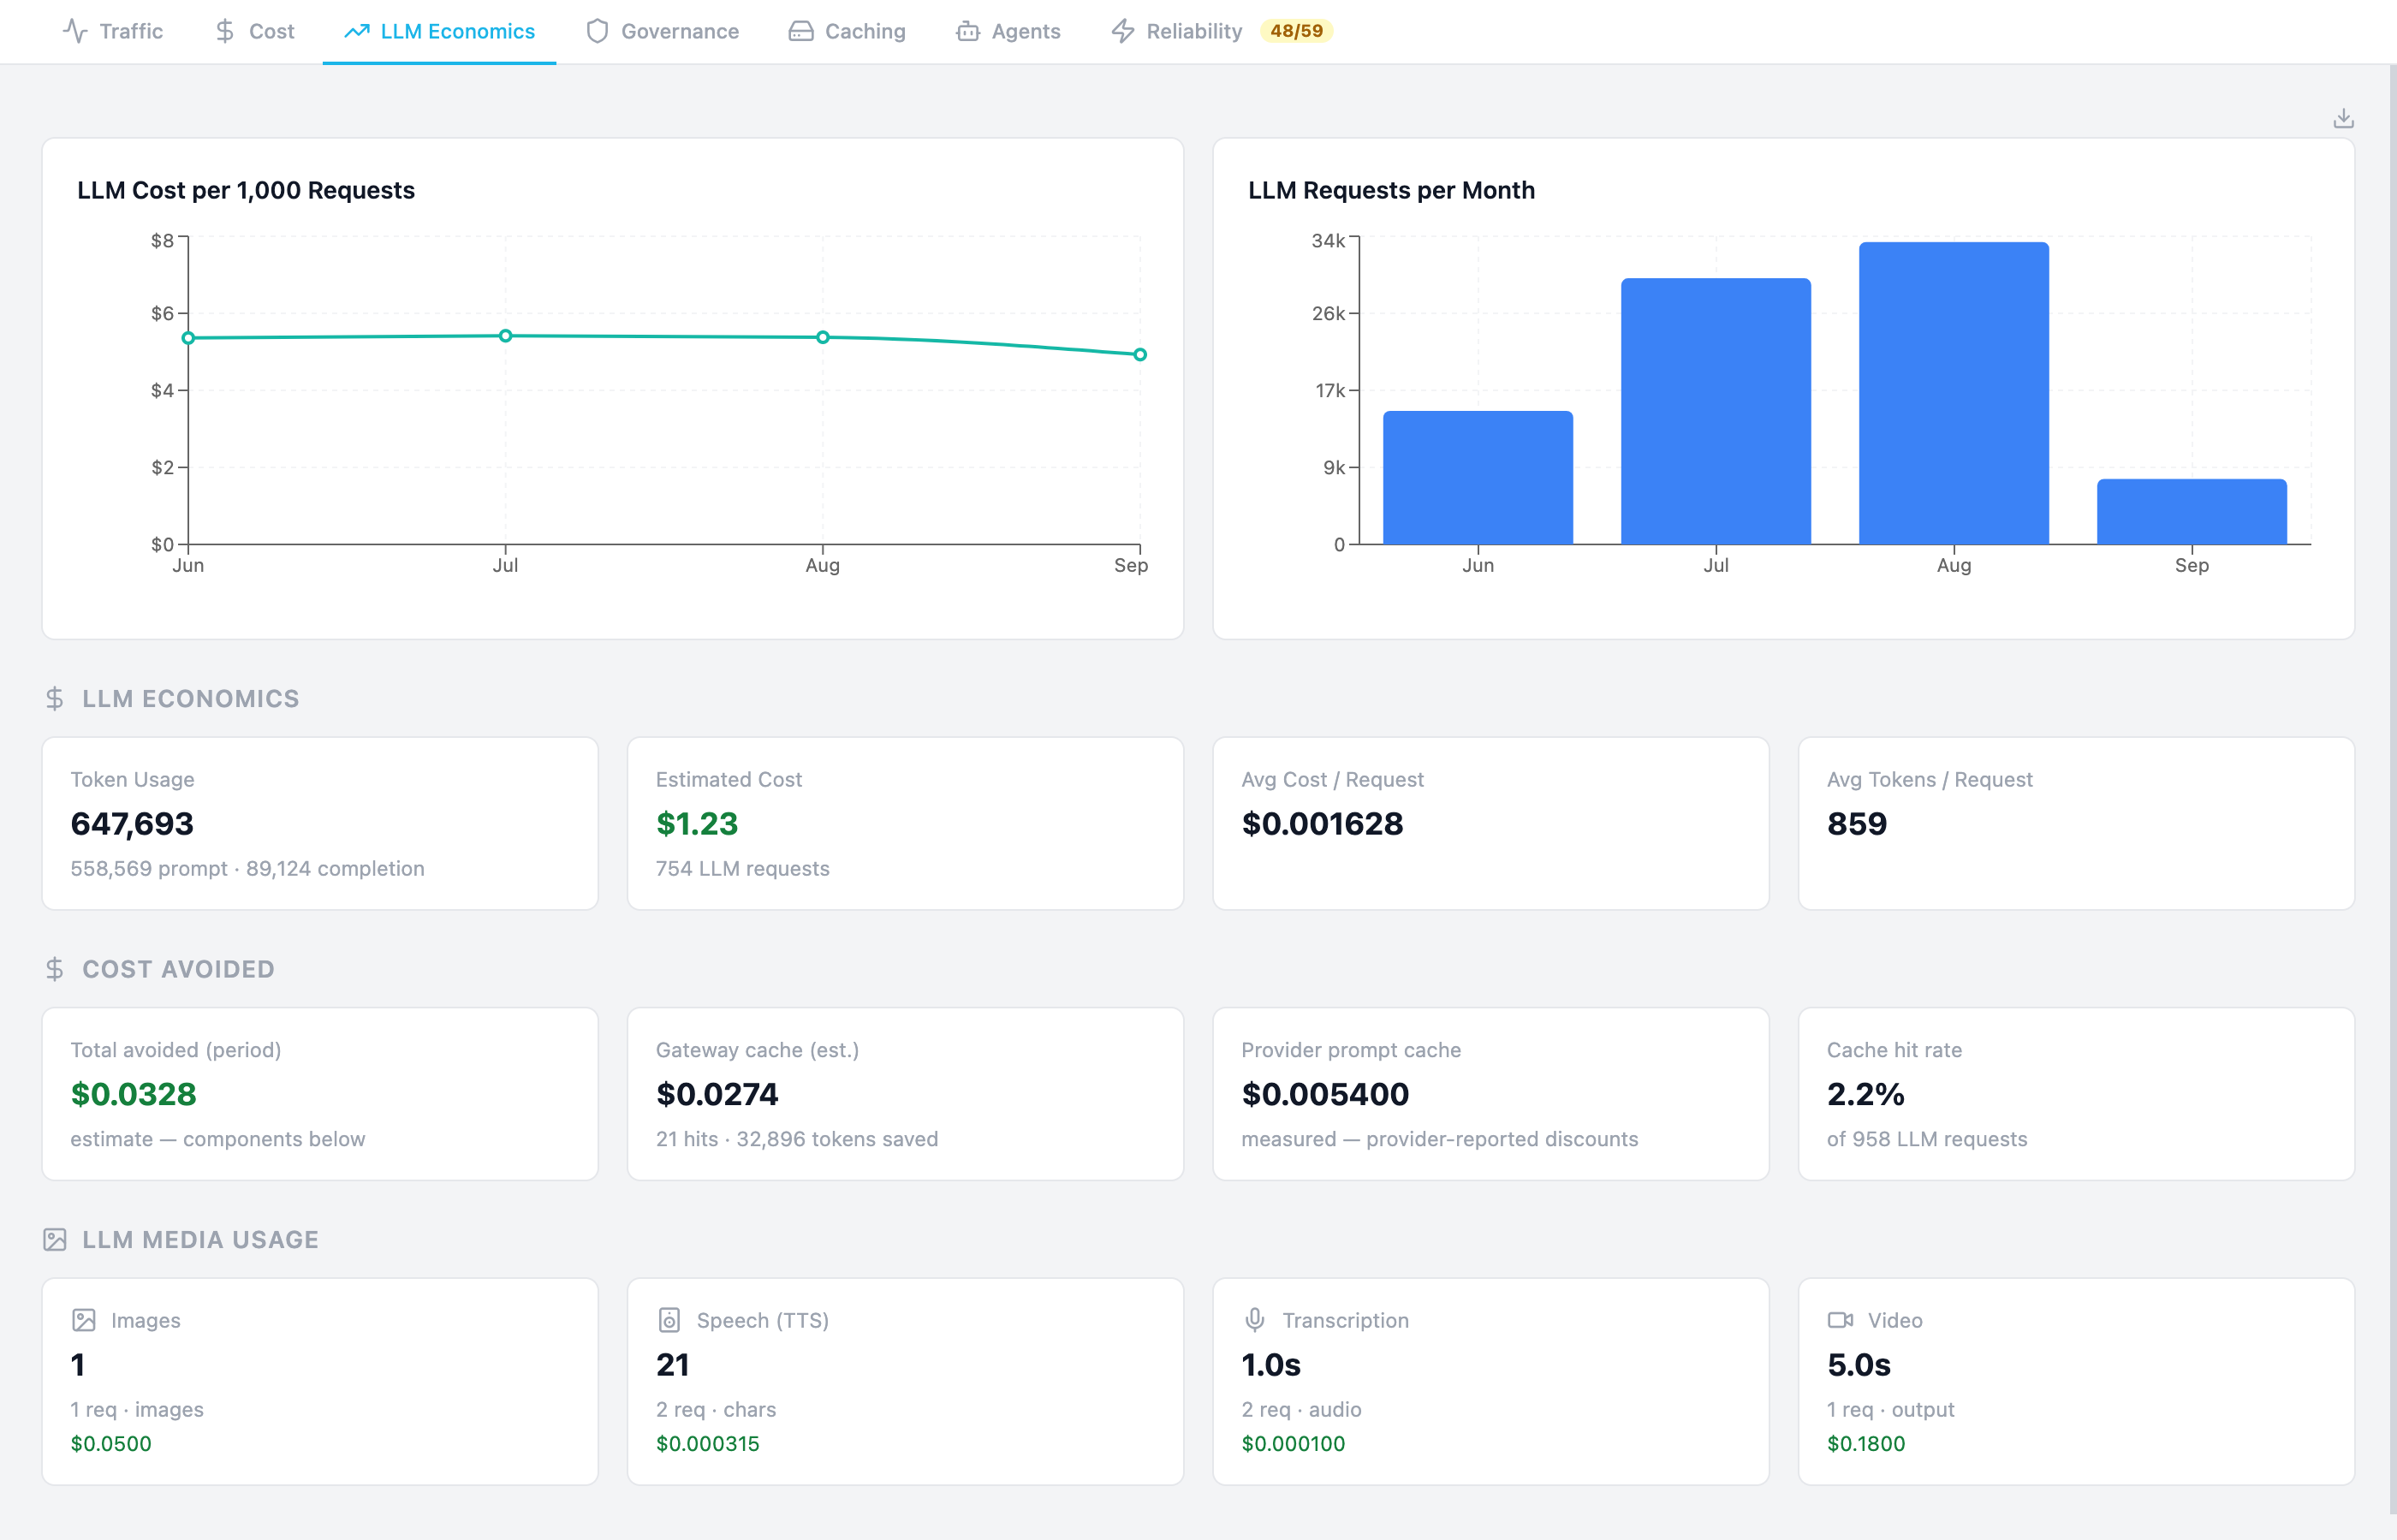
- Two-layer cache. Repeated and reworded prompts are answered from cache: no tokens, no provider call.
- Provider prompt caching, managed. Configured centrally, so long system prompts get the provider’s discount.
No runaway agents. No runaway budgets.
Agents can cause AI spend to get out of control. Brutor gives every agent an identity, a contract, enforced limits, and assurance while it runs.
01Identity
Every agent and skill is a named cost subject, not a shared API key.
02Contract
What it may touch, spend, and call. Expensive or risky actions need a human’s approval.
03Run
Per-agent budgets and per-skill quotas, enforced before the call. Cross the line and the call stops.
04Assured
Runs, drift, and conformance watched every day after launch. The assurance report writes itself.
The price of a result, and which workloads stay affordable as they grow.
Providers bill per call. Your business counts finished work. Tokenomics (a Linux Foundation standard since August 2026) measures the cost of a completed task, and how a workload’s cost grows with use. Brutor AI measures both from real runs and shows them on every AI System.
why brutor
Where Brutor AI FinOps stands out
Enforcement, not dashboards
01Most cost tools report after the spend. Brutor’s budgets act in the request path.
Agents are first-class cost subjects
02Every agent and skill attributed, limited, and gated, not one shared API key.
Optimization runs in the same pipeline
03Routing, caching, and batch work on the traffic the gateway already governs.
One ledger for the whole estate
04Routed and imported spend, cost per completed task, cost-growth class, and a flat annual license, no per-token fees.
Cost control is just a piece of the puzzle. Learn how you can manage your AI Systems with Brutor AI.